from nimrod.utils import set_seed
# seed for reproducible demos; not exported so importing the module leaves the global RNG alone
set_seed(42)AutoEncoders
Collection of Autoencoder models
Fashion MNIST
cfg = OmegaConf.load('../config/data/image/image.yaml')
dm = instantiate(cfg, name='fashion_mnist', data_dir='../data/image/')
dm.prepare_data()
dm.setup()
print(dm.num_classes)
[15:41:01] INFO - Init ImageDataModule for fashion_mnist--------------------------------------------------------------------------- HTTPError Traceback (most recent call last) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/huggingface_hub/utils/_http.py:406, in hf_raise_for_status(response, endpoint_name) 405 try: --> 406 response.raise_for_status() 407 except HTTPError as e: File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/requests/models.py:1024, in Response.raise_for_status(self) 1023 if http_error_msg: -> 1024 raise HTTPError(http_error_msg, response=self) HTTPError: 504 Server Error: Gateway Time-out for url: https://huggingface.co/api/datasets/zalando-datasets/fashion_mnist/paths-info/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2 The above exception was the direct cause of the following exception: HfHubHTTPError Traceback (most recent call last) Cell In[5], line 4 2 cfg = OmegaConf.load('../config/data/image/image.yaml') 3 dm = instantiate(cfg, name='fashion_mnist', data_dir='../data/image/') ----> 4 dm.prepare_data() 5 dm.setup() 6 print(dm.num_classes) File ~/Projects/nimrod/nimrod/image/datasets.py:415, in ImageDataModule.prepare_data(self) 412 """Download data if needed 413 """ 414 # train set --> 415 self.train_ds = ImageDataset( 416 self.hparams.name, 417 *self.args, 418 data_dir = self.hparams.data_dir, 419 split='train', 420 transforms = self.hparams.transforms, 421 **self.kwargs 422 ) 423 # get num classes before setup method converst ImageDataset to Subset 424 self._num_classes = self.train_ds.num_classes File ~/Projects/nimrod/nimrod/image/datasets.py:204, in ImageDataset.__init__(self, name, data_dir, split, transforms, streaming, exclude_grey_scale, verification_mode, from_image_folder, from_disk, *args) 202 self.exclude_grey_scale = exclude_grey_scale 203 if not from_image_folder: --> 204 self.info = load_dataset_builder(name, *args) 205 if split not in self.info.info.splits: 206 raise ValueError(f"The specified split '{split}' does not exist in the dataset '{name}'. Available splits: {list(self.info.info.splits.keys())}") File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/datasets/load.py:1886, in load_dataset_builder(path, name, data_dir, data_files, cache_dir, features, download_config, download_mode, revision, token, storage_options, trust_remote_code, _require_default_config_name, **config_kwargs) 1884 builder_cls = get_dataset_builder_class(dataset_module, dataset_name=dataset_name) 1885 # Instantiate the dataset builder -> 1886 builder_instance: DatasetBuilder = builder_cls( 1887 cache_dir=cache_dir, 1888 dataset_name=dataset_name, 1889 config_name=config_name, 1890 data_dir=data_dir, 1891 data_files=data_files, 1892 hash=dataset_module.hash, 1893 info=info, 1894 features=features, 1895 token=token, 1896 storage_options=storage_options, 1897 **builder_kwargs, 1898 **config_kwargs, 1899 ) 1900 builder_instance._use_legacy_cache_dir_if_possible(dataset_module) 1902 return builder_instance File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/datasets/builder.py:342, in DatasetBuilder.__init__(self, cache_dir, dataset_name, config_name, hash, base_path, info, features, token, repo_id, data_files, data_dir, storage_options, writer_batch_size, **config_kwargs) 340 config_kwargs["data_dir"] = data_dir 341 self.config_kwargs = config_kwargs --> 342 self.config, self.config_id = self._create_builder_config( 343 config_name=config_name, 344 custom_features=features, 345 **config_kwargs, 346 ) 348 # prepare info: DatasetInfo are a standardized dataclass across all datasets 349 # Prefill datasetinfo 350 if info is None: 351 # TODO FOR PACKAGED MODULES IT IMPORTS DATA FROM src/packaged_modules which doesn't make sense File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/datasets/builder.py:597, in DatasetBuilder._create_builder_config(self, config_name, custom_features, **config_kwargs) 594 raise ValueError(f"BuilderConfig must have a name, got {builder_config.name}") 596 # resolve data files if needed --> 597 builder_config._resolve_data_files( 598 base_path=self.base_path, 599 download_config=DownloadConfig(token=self.token, storage_options=self.storage_options), 600 ) 602 # compute the config id that is going to be used for caching 603 config_id = builder_config.create_config_id( 604 config_kwargs, 605 custom_features=custom_features, 606 ) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/datasets/builder.py:206, in BuilderConfig._resolve_data_files(self, base_path, download_config) 204 if isinstance(self.data_files, DataFilesPatternsDict): 205 base_path = xjoin(base_path, self.data_dir) if self.data_dir else base_path --> 206 self.data_files = self.data_files.resolve(base_path, download_config) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/datasets/data_files.py:818, in DataFilesPatternsDict.resolve(self, base_path, download_config) 816 out = DataFilesDict() 817 for key, data_files_patterns_list in self.items(): --> 818 out[key] = data_files_patterns_list.resolve(base_path, download_config) 819 return out File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/datasets/data_files.py:771, in DataFilesPatternsList.resolve(self, base_path, download_config) 768 for pattern, allowed_extensions in zip(self, self.allowed_extensions): 769 try: 770 data_files.extend( --> 771 resolve_pattern( 772 pattern, 773 base_path=base_path, 774 allowed_extensions=allowed_extensions, 775 download_config=download_config, 776 ) 777 ) 778 except FileNotFoundError: 779 if not has_magic(pattern): File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/datasets/data_files.py:388, in resolve_pattern(pattern, base_path, allowed_extensions, download_config) 383 if protocol == "hf" and config.HF_HUB_VERSION >= version.parse("0.20.0"): 384 # 10 times faster glob with detail=True (ignores costly info like lastCommit) 385 glob_kwargs["expand_info"] = False 386 matched_paths = [ 387 filepath if filepath.startswith(protocol_prefix) else protocol_prefix + filepath --> 388 for filepath, info in fs.glob(pattern, detail=True, **glob_kwargs).items() 389 if info["type"] == "file" 390 and (xbasename(filepath) not in files_to_ignore) 391 and not _is_inside_unrequested_special_dir(filepath, fs_pattern) 392 and not _is_unrequested_hidden_file_or_is_inside_unrequested_hidden_dir(filepath, fs_pattern) 393 ] # ignore .ipynb and __pycache__, but keep /../ 394 if allowed_extensions is not None: 395 out = [ 396 filepath 397 for filepath in matched_paths 398 if any("." + suffix in allowed_extensions for suffix in xbasename(filepath).split(".")[1:]) 399 ] File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/huggingface_hub/hf_file_system.py:521, in HfFileSystem.glob(self, path, **kwargs) 519 kwargs = {"expand_info": kwargs.get("detail", False), **kwargs} 520 path = self.resolve_path(path, revision=kwargs.get("revision")).unresolve() --> 521 return super().glob(path, **kwargs) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/fsspec/spec.py:611, in AbstractFileSystem.glob(self, path, maxdepth, **kwargs) 608 else: 609 depth = None --> 611 allpaths = self.find(root, maxdepth=depth, withdirs=True, detail=True, **kwargs) 613 pattern = glob_translate(path + ("/" if ends_with_sep else "")) 614 pattern = re.compile(pattern) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/huggingface_hub/hf_file_system.py:556, in HfFileSystem.find(self, path, maxdepth, withdirs, detail, refresh, revision, **kwargs) 533 """ 534 List all files below path. 535 (...) 553 `Union[List[str], Dict[str, Dict[str, Any]]]`: List of paths or dict of file information. 554 """ 555 if maxdepth: --> 556 return super().find( 557 path, maxdepth=maxdepth, withdirs=withdirs, detail=detail, refresh=refresh, revision=revision, **kwargs 558 ) 559 resolved_path = self.resolve_path(path, revision=revision) 560 path = resolved_path.unresolve() File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/fsspec/spec.py:502, in AbstractFileSystem.find(self, path, maxdepth, withdirs, detail, **kwargs) 499 # Add the root directory if withdirs is requested 500 # This is needed for posix glob compliance 501 if withdirs and path != "" and self.isdir(path): --> 502 out[path] = self.info(path) 504 for _, dirs, files in self.walk(path, maxdepth, detail=True, **kwargs): 505 if withdirs: File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/huggingface_hub/hf_file_system.py:719, in HfFileSystem.info(self, path, refresh, revision, **kwargs) 717 out = out1[0] 718 if refresh or out is None or (expand_info and out and out["last_commit"] is None): --> 719 paths_info = self._api.get_paths_info( 720 resolved_path.repo_id, 721 resolved_path.path_in_repo, 722 expand=expand_info, 723 revision=resolved_path.revision, 724 repo_type=resolved_path.repo_type, 725 ) 726 if not paths_info: 727 _raise_file_not_found(path, None) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/huggingface_hub/utils/_validators.py:114, in validate_hf_hub_args.<locals>._inner_fn(*args, **kwargs) 111 if check_use_auth_token: 112 kwargs = smoothly_deprecate_use_auth_token(fn_name=fn.__name__, has_token=has_token, kwargs=kwargs) --> 114 return fn(*args, **kwargs) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/huggingface_hub/hf_api.py:3303, in HfApi.get_paths_info(self, repo_id, paths, expand, revision, repo_type, token) 3293 headers = self._build_hf_headers(token=token) 3295 response = get_session().post( 3296 f"{self.endpoint}/api/{repo_type}s/{repo_id}/paths-info/{revision}", 3297 data={ (...) 3301 headers=headers, 3302 ) -> 3303 hf_raise_for_status(response) 3304 paths_info = response.json() 3305 return [ 3306 RepoFile(**path_info) if path_info["type"] == "file" else RepoFolder(**path_info) 3307 for path_info in paths_info 3308 ] File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/huggingface_hub/utils/_http.py:477, in hf_raise_for_status(response, endpoint_name) 473 raise _format(HfHubHTTPError, message, response) from e 475 # Convert `HTTPError` into a `HfHubHTTPError` to display request information 476 # as well (request id and/or server error message) --> 477 raise _format(HfHubHTTPError, str(e), response) from e HfHubHTTPError: 504 Server Error: Gateway Time-out for url: https://huggingface.co/api/datasets/zalando-datasets/fashion_mnist/paths-info/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
dm.show_grid(3,3)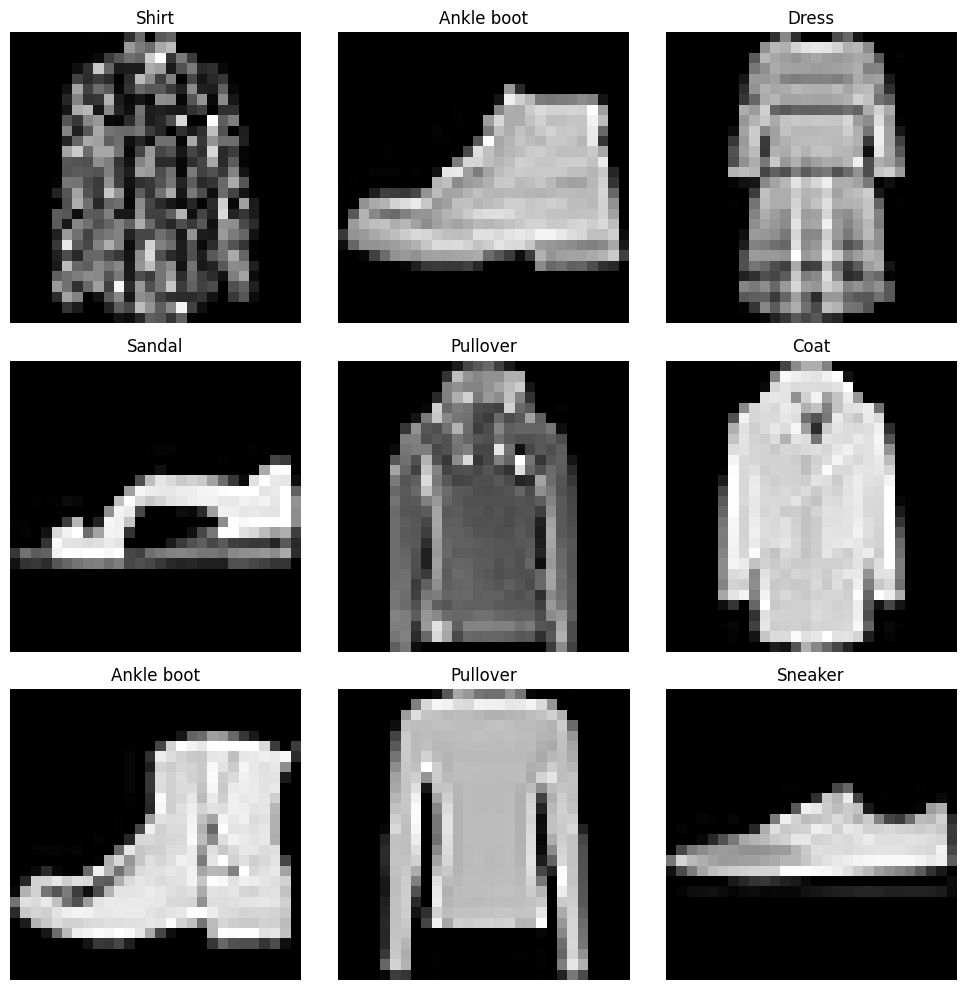
print(dm.label_names)--------------------------------------------------------------------------- RuntimeError Traceback (most recent call last) Cell In[6], line 2 1 #| notest ----> 2 print(dm.label_names) File ~/Projects/nimrod/nimrod/image/datasets.py:409, in ImageDataModule.label_names(self) 407 if self.train_ds is not None: 408 return self._label_names --> 409 raise RuntimeError("train_ds is not initialized. Call prepare_data() first.") RuntimeError: train_ds is not initialized. Call prepare_data() first.
ConvNet
cfg = OmegaConf.load('../config/model/image/convnetx_adam.yaml')
# nnet = instantiate(cfg.nnet, num_classes=dm.num_classes)
# optimizer = instantiate(cfg.optimizer)
# scheduler = instantiate(cfg.scheduler)

# model = ConvNetX(nnet, dm.num_classes, optimizer, scheduler)
model = instantiate(cfg, num_classes=10)(optimizer=instantiate(OmegaConf.load('../config/optimizer/adam_w.yaml')), scheduler=None)
[15:41:17] INFO - ConvNetX: init
[15:41:17] INFO - Classifier: initMAX_EPOCHS = 5
dm.batch_size = 256
print(dm.batch_size)
# lr = 0.4
trainer = Trainer(
max_epochs=MAX_EPOCHS,
logger=CSVLogger("logs", name="fashion_mnist_convnet"),
callbacks = [LearningRateMonitor(logging_interval="step")],
check_val_every_n_epoch=1,
log_every_n_steps=1
)GPU available: True (cuda), used: True
TPU available: False, using: 0 TPU cores
HPU available: False, using: 0 HPUs256LR Finder
tuner = Tuner(trainer)
lr_finder = tuner.lr_find(
    model,
    datamodule=dm,
    min_lr=1e-6,
    max_lr=1.0,
    num_training=100,  # number of iterations
    # attr_name="optimizer.lr",
)
fig = lr_finder.plot(suggest=True)
plt.show()
print(f"Suggested learning rate: {lr_finder.suggestion()}")
You are using a CUDA device ('NVIDIA GeForce RTX 4090') that has Tensor Cores. To properly utilize them, you should set `torch.set_float32_matmul_precision('medium' | 'high')` which will trade-off precision for performance. For more details, read https://pytorch.org/docs/stable/generated/torch.set_float32_matmul_precision.html#torch.set_float32_matmul_precision
[22:43:36] INFO - loading dataset fashion_mnist with args () from split train
[22:43:36] INFO - loading dataset fashion_mnist from split train
Overwrite dataset info from restored data version if exists.
[22:43:37] INFO - Overwrite dataset info from restored data version if exists.
Loading Dataset info from ../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
[22:43:37] INFO - Loading Dataset info from ../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
Found cached dataset fashion_mnist (/user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2)
[22:43:37] INFO - Found cached dataset fashion_mnist (/user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2)
Loading Dataset info from /user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
[22:43:37] INFO - Loading Dataset info from /user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
[22:43:41] INFO - loading dataset fashion_mnist with args () from split test
[22:43:41] INFO - loading dataset fashion_mnist from split test
Overwrite dataset info from restored data version if exists.
[22:43:43] INFO - Overwrite dataset info from restored data version if exists.
Loading Dataset info from ../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
[22:43:43] INFO - Loading Dataset info from ../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
Found cached dataset fashion_mnist (/user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2)
[22:43:43] INFO - Found cached dataset fashion_mnist (/user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2)
Loading Dataset info from /user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
[22:43:43] INFO - Loading Dataset info from /user/s/slegroux/Projects/nimrod/nbs/../data/image/fashion_mnist/fashion_mnist/0.0.0/531be5e2ccc9dba0c201ad3ae567a4f3d16ecdd2
LOCAL_RANK: 0 - CUDA_VISIBLE_DEVICES: [0]
[22:43:43] INFO - Optimizer: <class 'torch.optim.adam.Adam'>
[22:43:43] INFO - Scheduler: <class 'torch.optim.lr_scheduler.ReduceLROnPlateau'>
/user/s/slegroux/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/core/optimizer.py:317: The lr scheduler dict contains the key(s) ['monitor'], but the keys will be ignored. You need to call `lr_scheduler.step()` manually in manual optimization.
/user/s/slegroux/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:425: The 'train_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=23` in the `DataLoader` to improve performance.
/user/s/slegroux/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:425: The 'val_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=23` in the `DataLoader` to improve performance.--------------------------------------------------------------------------- RuntimeError Traceback (most recent call last) Cell In[12], line 3 1 #| notest 2 tuner = Tuner(trainer) ----> 3 lr_finder = tuner.lr_find( 4 model, 5 datamodule=dm, 6 min_lr=1e-6, 7 max_lr=1.0, 8 num_training=100, # number of iterations 9 # attr_name="optimizer.lr", 10 ) 11 fig = lr_finder.plot(suggest=True) 12 plt.show() File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/tuner/tuning.py:180, in Tuner.lr_find(self, model, train_dataloaders, val_dataloaders, dataloaders, datamodule, method, min_lr, max_lr, num_training, mode, early_stop_threshold, update_attr, attr_name) 177 lr_finder_callback._early_exit = True 178 self._trainer.callbacks = [lr_finder_callback] + self._trainer.callbacks --> 180 self._trainer.fit(model, train_dataloaders, val_dataloaders, datamodule) 182 self._trainer.callbacks = [cb for cb in self._trainer.callbacks if cb is not lr_finder_callback] 184 return lr_finder_callback.optimal_lr File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/trainer.py:539, in Trainer.fit(self, model, train_dataloaders, val_dataloaders, datamodule, ckpt_path) 537 self.state.status = TrainerStatus.RUNNING 538 self.training = True --> 539 call._call_and_handle_interrupt( 540 self, self._fit_impl, model, train_dataloaders, val_dataloaders, datamodule, ckpt_path 541 ) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/call.py:47, in _call_and_handle_interrupt(trainer, trainer_fn, *args, **kwargs) 45 if trainer.strategy.launcher is not None: 46 return trainer.strategy.launcher.launch(trainer_fn, *args, trainer=trainer, **kwargs) ---> 47 return trainer_fn(*args, **kwargs) 49 except _TunerExitException: 50 _call_teardown_hook(trainer) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/trainer.py:575, in Trainer._fit_impl(self, model, train_dataloaders, val_dataloaders, datamodule, ckpt_path) 568 assert self.state.fn is not None 569 ckpt_path = self._checkpoint_connector._select_ckpt_path( 570 self.state.fn, 571 ckpt_path, 572 model_provided=True, 573 model_connected=self.lightning_module is not None, 574 ) --> 575 self._run(model, ckpt_path=ckpt_path) 577 assert self.state.stopped 578 self.training = False File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/trainer.py:962, in Trainer._run(self, model, ckpt_path) 960 # hook 961 if self.state.fn == TrainerFn.FITTING: --> 962 call._call_callback_hooks(self, "on_fit_start") 963 call._call_lightning_module_hook(self, "on_fit_start") 965 _log_hyperparams(self) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/call.py:222, in _call_callback_hooks(trainer, hook_name, monitoring_callbacks, *args, **kwargs) 220 if callable(fn): 221 with trainer.profiler.profile(f"[Callback]{callback.state_key}.{hook_name}"): --> 222 fn(trainer, trainer.lightning_module, *args, **kwargs) 224 if pl_module: 225 # restore current_fx when nested context 226 pl_module._current_fx_name = prev_fx_name File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/callbacks/lr_finder.py:130, in LearningRateFinder.on_fit_start(self, trainer, pl_module) 128 @override 129 def on_fit_start(self, trainer: "pl.Trainer", pl_module: "pl.LightningModule") -> None: --> 130 self.lr_find(trainer, pl_module) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/callbacks/lr_finder.py:113, in LearningRateFinder.lr_find(self, trainer, pl_module) 111 def lr_find(self, trainer: "pl.Trainer", pl_module: "pl.LightningModule") -> None: 112 with isolate_rng(): --> 113 self.optimal_lr = _lr_find( 114 trainer, 115 pl_module, 116 min_lr=self._min_lr, 117 max_lr=self._max_lr, 118 num_training=self._num_training_steps, 119 mode=self._mode, 120 early_stop_threshold=self._early_stop_threshold, 121 update_attr=self._update_attr, 122 attr_name=self._attr_name, 123 ) 125 if self._early_exit: 126 raise _TunerExitException() File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/tuner/lr_finder.py:278, in _lr_find(trainer, model, min_lr, max_lr, num_training, mode, early_stop_threshold, update_attr, attr_name) 275 lr_finder._exchange_scheduler(trainer) 277 # Fit, lr & loss logged in callback --> 278 _try_loop_run(trainer, params) 280 # Prompt if we stopped early 281 if trainer.global_step != num_training + start_steps: File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/tuner/lr_finder.py:523, in _try_loop_run(trainer, params) 521 loop.load_state_dict(deepcopy(params["loop_state_dict"])) 522 loop.restarting = False --> 523 loop.run() File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/loops/fit_loop.py:216, in _FitLoop.run(self) 214 try: 215 self.on_advance_start() --> 216 self.advance() 217 self.on_advance_end() 218 except StopIteration: File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/loops/fit_loop.py:455, in _FitLoop.advance(self) 453 with self.trainer.profiler.profile("run_training_epoch"): 454 assert self._data_fetcher is not None --> 455 self.epoch_loop.run(self._data_fetcher) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/loops/training_epoch_loop.py:150, in _TrainingEpochLoop.run(self, data_fetcher) 148 while not self.done: 149 try: --> 150 self.advance(data_fetcher) 151 self.on_advance_end(data_fetcher) 152 except StopIteration: File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/loops/training_epoch_loop.py:322, in _TrainingEpochLoop.advance(self, data_fetcher) 320 batch_output = self.automatic_optimization.run(trainer.optimizers[0], batch_idx, kwargs) 321 else: --> 322 batch_output = self.manual_optimization.run(kwargs) 324 self.batch_progress.increment_processed() 326 # update non-plateau LR schedulers 327 # update epoch-interval ones only when we are at the end of training epoch File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/loops/optimization/manual.py:94, in _ManualOptimization.run(self, kwargs) 92 self.on_run_start() 93 with suppress(StopIteration): # no loop to break at this level ---> 94 self.advance(kwargs) 95 self._restarting = False 96 return self.on_run_end() File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/loops/optimization/manual.py:114, in _ManualOptimization.advance(self, kwargs) 111 trainer = self.trainer 113 # manually capture logged metrics --> 114 training_step_output = call._call_strategy_hook(trainer, "training_step", *kwargs.values()) 115 del kwargs # release the batch from memory 116 self.trainer.strategy.post_training_step() # unused hook - call anyway for backward compatibility File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/call.py:323, in _call_strategy_hook(trainer, hook_name, *args, **kwargs) 320 return None 322 with trainer.profiler.profile(f"[Strategy]{trainer.strategy.__class__.__name__}.{hook_name}"): --> 323 output = fn(*args, **kwargs) 325 # restore current_fx when nested context 326 pl_module._current_fx_name = prev_fx_name File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/strategies/strategy.py:391, in Strategy.training_step(self, *args, **kwargs) 389 if self.model != self.lightning_module: 390 return self._forward_redirection(self.model, self.lightning_module, "training_step", *args, **kwargs) --> 391 return self.lightning_module.training_step(*args, **kwargs) File ~/Projects/nimrod/nimrod/models/core.py:186, in Classifier.training_step(self, batch, batch_idx) 183 sched.step() #reduce plateau sched is updated at end of epoch only instead TODO: should it be applied to val loop by default? 185 self.train_loss(loss) --> 186 self.train_acc(preds, y) 187 metrics = {"train/loss": self.train_loss, "train/acc": self.train_acc} 188 self.log_dict(metrics, on_epoch=True, on_step=True, prog_bar=True)# Pass the validation loss to the scheduler File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torch/nn/modules/module.py:1532, in Module._wrapped_call_impl(self, *args, **kwargs) 1530 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1531 else: -> 1532 return self._call_impl(*args, **kwargs) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torch/nn/modules/module.py:1541, in Module._call_impl(self, *args, **kwargs) 1536 # If we don't have any hooks, we want to skip the rest of the logic in 1537 # this function, and just call forward. 1538 if not (self._backward_hooks or self._backward_pre_hooks or self._forward_hooks or self._forward_pre_hooks 1539 or _global_backward_pre_hooks or _global_backward_hooks 1540 or _global_forward_hooks or _global_forward_pre_hooks): -> 1541 return forward_call(*args, **kwargs) 1543 try: 1544 result = None File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torchmetrics/metric.py:316, in Metric.forward(self, *args, **kwargs) 314 self._forward_cache = self._forward_full_state_update(*args, **kwargs) 315 else: --> 316 self._forward_cache = self._forward_reduce_state_update(*args, **kwargs) 318 return self._forward_cache File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torchmetrics/metric.py:385, in Metric._forward_reduce_state_update(self, *args, **kwargs) 382 self._enable_grad = True # allow grads for batch computation 384 # calculate batch state and compute batch value --> 385 self.update(*args, **kwargs) 386 batch_val = self.compute() 388 # reduce batch and global state File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torchmetrics/metric.py:560, in Metric._wrap_update.<locals>.wrapped_func(*args, **kwargs) 552 if "Expected all tensors to be on" in str(err): 553 raise RuntimeError( 554 "Encountered different devices in metric calculation (see stacktrace for details)." 555 " This could be due to the metric class not being on the same device as input." (...) 558 " device corresponds to the device of the input." 559 ) from err --> 560 raise err 562 if self.compute_on_cpu: 563 self._move_list_states_to_cpu() File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torchmetrics/metric.py:550, in Metric._wrap_update.<locals>.wrapped_func(*args, **kwargs) 548 with torch.set_grad_enabled(self._enable_grad): 549 try: --> 550 update(*args, **kwargs) 551 except RuntimeError as err: 552 if "Expected all tensors to be on" in str(err): File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torchmetrics/classification/stat_scores.py:339, in MulticlassStatScores.update(self, preds, target) 337 """Update state with predictions and targets.""" 338 if self.validate_args: --> 339 _multiclass_stat_scores_tensor_validation( 340 preds, target, self.num_classes, self.multidim_average, self.ignore_index 341 ) 342 preds, target = _multiclass_stat_scores_format(preds, target, self.top_k) 343 tp, fp, tn, fn = _multiclass_stat_scores_update( 344 preds, target, self.num_classes, self.top_k, self.average, self.multidim_average, self.ignore_index 345 ) File ~/miniconda3/envs/nimrod/lib/python3.11/site-packages/torchmetrics/functional/classification/stat_scores.py:318, in _multiclass_stat_scores_tensor_validation(preds, target, num_classes, multidim_average, ignore_index) 316 num_unique_values = len(torch.unique(t, dim=None)) 317 if num_unique_values > check_value: --> 318 raise RuntimeError( 319 f"Detected more unique values in `{name}` than expected. Expected only {check_value} but found" 320 f" {num_unique_values} in `{name}`. Found values: {torch.unique(t, dim=None)}." 321 ) RuntimeError: Detected more unique values in `preds` than expected. Expected only 10 but found 30 in `preds`. Found values: tensor([ 0, 1, 3, 6, 7, 8, 9, 10, 11, 13, 14, 15, 16, 17, 19, 20, 21, 22, 23, 25, 27, 28, 29, 30, 31, 32, 33, 34, 38, 39], device='cuda:0').
# print(f"lr: {model.lr}, bs: {dm.batch_size}")lr: 9.120108393559098e-06, bs: 256Fit
cfg.optimizer.lr = 0.4
print(OmegaConf.to_yaml(cfg))

model = instantiate(cfg)
trainer.fit(model, dm.train_dataloader(), dm.val_dataloader())
[22:10:36] INFO - ConvNetX: init
[22:10:36] INFO - Classifier: init_target_: nimrod.models.conv.ConvNetX
num_classes: 10
nnet:
_target_: nimrod.models.conv.ConvNet
n_features:
- 1
- 8
- 16
- 32
- 64
num_classes: ${..num_classes}
kernel_size: 3
bias: null
normalization:
_target_: hydra.utils.get_class
path: torch.nn.BatchNorm2d
activation:
_target_: hydra.utils.get_class
path: torch.nn.ReLU
optimizer:
_target_: torch.optim.Adam
_partial_: true
lr: 0.4
scheduler:
_target_: torch.optim.lr_scheduler.ReduceLROnPlateau
_partial_: true
mode: min
factor: 0.1
patience: 5
/Users/slegroux/miniforge3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/utilities/parsing.py:208: Attribute 'nnet' is an instance of `nn.Module` and is already saved during checkpointing. It is recommended to ignore them using `self.save_hyperparameters(ignore=['nnet'])`.
[22:10:54] INFO - Optimizer: Adam (
Parameter Group 0
    amsgrad: False
    betas: (0.9, 0.999)
    capturable: False
    differentiable: False
    eps: 1e-08
    foreach: None
    fused: None
    lr: 0.4
    maximize: False
    weight_decay: 0
)
[22:10:54] INFO - Scheduler: <torch.optim.lr_scheduler.ReduceLROnPlateau object>

  | Name         | Type               | Params | Mode
------------------------------------------------------------
0 | loss         | CrossEntropyLoss   | 0      | train
1 | train_acc    | MulticlassAccuracy | 0      | train
2 | val_acc      | MulticlassAccuracy | 0      | train
3 | test_acc     | MulticlassAccuracy | 0      | train
4 | train_loss   | MeanMetric         | 0      | train
5 | val_loss     | MeanMetric         | 0      | train
6 | test_loss    | MeanMetric         | 0      | train
7 | val_acc_best | MaxMetric          | 0      | train
8 | nnet         | ConvNet            | 30.3 K | train
------------------------------------------------------------
30.3 K    Trainable params
0         Non-trainable params
30.3 K    Total params
0.121     Total estimated model params size (MB)
34        Modules in train mode
0         Modules in eval mode
[22:11:24] INFO - scheduler is an instance of Reduce plateau[22:11:54] INFO - scheduler is an instance of Reduce plateau[22:12:24] INFO - scheduler is an instance of Reduce plateau[22:12:55] INFO - scheduler is an instance of Reduce plateau[22:13:25] INFO - scheduler is an instance of Reduce plateau
`Trainer.fit` stopped: `max_epochs=5` reached.########################
csv_path = f"{trainer.logger.log_dir}/metrics.csv"
metrics = pd.read_csv(csv_path)
metrics.head()
#########################
plt.figure()
plt.plot(metrics['step'], metrics['train/loss_step'], 'b.-')
plt.plot(metrics['step'], metrics['val/loss'],'r.-')
plt.figure()
plt.plot(metrics['step'], metrics['lr-Adam'], 'g.-')
plt.show()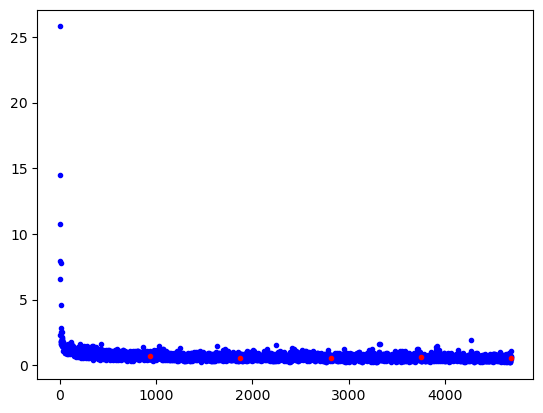
trainer.test(model, dm.test_dataloader())/Users/slegroux/miniforge3/envs/nimrod/lib/python3.11/site-packages/lightning/pytorch/trainer/connectors/data_connector.py:424: The 'test_dataloader' does not have many workers which may be a bottleneck. Consider increasing the value of the `num_workers` argument` to `num_workers=11` in the `DataLoader` to improve performance.┏━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━┓ ┃ Test metric ┃ DataLoader 0 ┃ ┡━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━┩ │ test/acc │ 0.803600013256073 │ │ test/loss │ 0.5951264500617981 │ └───────────────────────────┴───────────────────────────┘
[{'test/loss': 0.5951264500617981, 'test/acc': 0.803600013256073}]FC Autoencoder
class LinearEncoder(nn.Module):
    def __init__(self):
        super().__init__()
        self.l1 = nn.Sequential(nn.Linear(28 * 28, 64), nn.ReLU(), nn.Linear(64, 3))

    def forward(self, x):
        return self.l1(x)


class LinearDecoder(nn.Module):
    def __init__(self):
        super().__init__()
        self.l1 = nn.Sequential(nn.Linear(3, 64), nn.ReLU(), nn.Linear(64, 28 * 28))

    def forward(self, x):
        return self.l1(x)
enc = LinearEncoder()
dec = LinearDecoder()
a = AutoEncoder(enc, dec)
batch = torch.rand((5, 3, 28*28))
encoded = enc(batch)
print(encoded.shape)
# y = a(batch)
# print(y.shape)torch.Size([5, 3, 3])ds = ImageDataset(name='fashion_mnist', data_dir='../data/image/')
dl = DataLoader(ds, batch_size=3)
b = next(iter(dl))
print(f" X: {b[0].shape}, Y: {b[1].shape}") X: torch.Size([3, 1, 28, 28]), Y: torch.Size([3])acfg = OmegaConf.load('../config/data/image/image.yaml')
dm = instantiate(cfg, name='fashion_mnist', data_dir='../data/image/')
dm.prepare_data()
dm.setup()
# print(f"num classes: {dm.num_classes}, bs: {dm.batch_size}, labels: {dm.label_names}" if dm.label_names else f"num classes: {dm.num_classes}")[14:58:07] INFO - Init ImageDataModule for fashion_mnist
[14:58:22] INFO - split train into train/val [0.8, 0.2]
[14:58:22] INFO - train: 48000 val: 12000, test: 10000device = get_device()
print(f"Device: {device}")
enc = LinearEncoder()
dec =LinearDecoder()
model = AutoEncoder(enc, dec).to(device)[14:55:26] INFO - Using device: mpsDevice: mpscriterion = nn.MSELoss()
optimizer = torch.optim.Adam(model.parameters(), lr=0.001)
N_EPOCHS = 5
for epoch in range(N_EPOCHS):
i = 0
model.train()
for images, labels in dm.train_dataloader():
optimizer.zero_grad()
images, labels = images.to(device), labels.to(device)
# B x C x H x W -> B x C x L
images = images.view(-1, images.size(2) * images.size(3))
outputs = model(images)
# output should be as close to input as possible
loss = criterion(outputs, images)
loss.backward()
optimizer.step()
model.eval()
with torch.no_grad():
total_loss, epoch_step = 0, 0
for images, labels in dm.val_dataloader():
images, labels = images.to(device), labels.to(device)
images = images.view(-1, images.size(2) * images.size(3))
outputs = model(images)
eval_loss = criterion(outputs, images)
epoch_len = len(images)
epoch_step += epoch_len
total_loss += eval_loss.item() * epoch_len
logger.info(f"Epoch: {epoch}, len: {epoch_len}, Loss: {total_loss / epoch_step:.3f}")[14:56:24] INFO - Epoch: 0, len: 32, Loss: 0.025
[14:56:27] INFO - Epoch: 1, len: 32, Loss: 0.025
[14:56:31] INFO - Epoch: 2, len: 32, Loss: 0.025
[14:56:35] INFO - Epoch: 3, len: 32, Loss: 0.025
[14:56:39] INFO - Epoch: 4, len: 32, Loss: 0.025x, y = next(iter(dm.train_dataloader()))
print(f" X: {x.shape}, Y: {y.shape}")
x = x.to(device)
B, C, H, W = x.shape
x_hat = model(x.view(-1, H * W)).view(-1, C, H, W)
print(f" X_hat: {x_hat.shape}")
idx = 0
n_rows, n_cols = 1, 2
fig, axs = plt.subplots(n_rows, n_cols, figsize=(10, 10))
axs[0].imshow(x[idx].permute(1, 2, 0).cpu().numpy(), cmap='gray')
axs[1].imshow(x_hat[idx].permute(1, 2, 0).detach().cpu().numpy(), cmap='gray')
plt.show() X: torch.Size([64, 1, 28, 28]), Y: torch.Size([64])
X_hat: torch.Size([64, 1, 28, 28])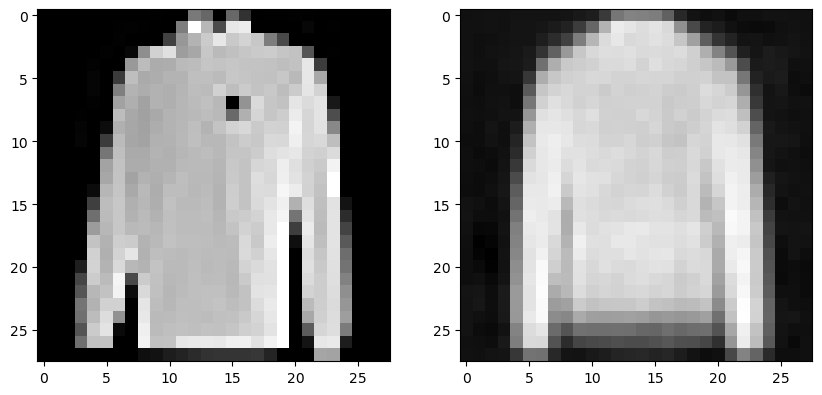
ConvNet Autoencoder
class ConvEncoder(nn.Module):
    def __init__(self):
        super().__init__()
        layers = nn.ModuleList()
        # X -> B,C,28,28
        layers.append(nn.ZeroPad2d(2)) # X -> B,C,32,32
        layers.append(ConvBlock(1,2, normalization=None)) # 16 x 16
        layers.append(ConvBlock(2,4, normalization=None)) # 8 x 8
        self._nnet = nn.Sequential(*layers)

    def forward(self, x:torch.Tensor)->torch.Tensor:
        return self._nnet(x)
class ConvDecoder(nn.Module):
def __init__(self):
super().__init__()
layers = nn.ModuleList()
layers.append(DeconvBlock(4,2, normalization=None)) # 16 x 16
layers.append(DeconvBlock(2,1, normalization=None, activation=None)) # 32 x 32
layers.append(nn.ZeroPad2d(-2)) # 28 x 28
layers.append(nn.Sigmoid())
self._nnet = nn.Sequential(*layers)
def forward(self, x:torch.Tensor)->torch.Tensor:
return self._nnet(x)device = get_device()
print(f"Device: {device}")
enc = ConvEncoder()
dec = ConvDecoder()
model = AutoEncoder(enc, dec).to(device)[22:44:23] INFO - Using device: cudaDevice: cudacriterion = nn.MSELoss()
optimizer = torch.optim.Adam(model.parameters(), lr=0.001)
N_EPOCHS = 5
for epoch in range(N_EPOCHS):
i = 0
model.train()
for images, labels in dm.train_dataloader():
optimizer.zero_grad()
images, labels = images.to(device), labels.to(device)
# images = images.view(-1, images.size(2) * images.size(3))
outputs = model(images)
# output should be as close to input as possible
loss = criterion(outputs, images)
loss.backward()
optimizer.step()
model.eval()
with torch.no_grad():
total_loss, epoch_step = 0, 0
for images, labels in dm.val_dataloader():
images, labels = images.to(device), labels.to(device)
# images = images.view(-1, images.size(2) * images.size(3))
outputs = model(images)
eval_loss = criterion(outputs, images)
epoch_len = len(images)
epoch_step += epoch_len
total_loss += eval_loss.item() * epoch_len
logger.info(f"Epoch: {epoch}, len: {epoch_len}, Loss: {total_loss / epoch_step:.3f}")[15:34:38] INFO - Epoch: 0, len: 32, Loss: 0.012
[15:34:43] INFO - Epoch: 1, len: 32, Loss: 0.011
[15:34:48] INFO - Epoch: 2, len: 32, Loss: 0.011
[15:34:53] INFO - Epoch: 3, len: 32, Loss: 0.011
[15:34:59] INFO - Epoch: 4, len: 32, Loss: 0.011x, y = next(iter(dm.train_dataloader()))
print(f" X: {x.shape}, Y: {y.shape}")
x = x.to(device)
B, C, H, W = x.shape
x_hat = model(x)
print(f" X_hat: {x_hat.shape}")
idx = 0
n_rows, n_cols = 1, 2
fig, axs = plt.subplots(n_rows, n_cols, figsize=(10, 10))
axs[0].imshow(x[idx].permute(1, 2, 0).cpu().numpy(), cmap='gray')
axs[1].imshow(x_hat[idx].permute(1, 2, 0).detach().cpu().numpy(), cmap='gray')
plt.show() X: torch.Size([64, 1, 28, 28]), Y: torch.Size([64])
X_hat: torch.Size([64, 1, 28, 28])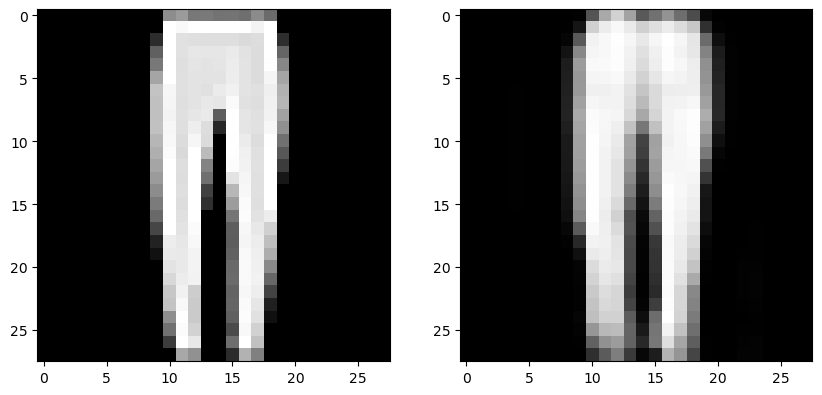
AutoEncoder_X
#show_doc(AutoEncoderPL.forward)AutoEncoderPL.forward
AutoEncoderPL.forward (x:torch.Tensor)
Forward pass of the AutoEncoder model.
| Type | Details | |
|---|---|---|
| x | Tensor | Tensor B x L |
| Returns | Tensor | Reconstructed input tensor of shape B x L |
autoencoder_pl = AutoEncoderPL(a)
b = torch.rand((5,28*28))
y = autoencoder_pl(b)
print(y.shape)
torch.Size([5, 784])